GPT-6 gives developers three useful operating points: Astra for the hardest work, Sol for capable everyday coding and agent workflows, and Luna for focused tasks at high volume. The right choice is not simply the model with the lowest token price. It is the least expensive model that completes your real task reliably, with acceptable latency and review effort.
An agent may read a large repository, call tools repeatedly, generate hidden reasoning tokens, inspect its own changes, and retry after a failed command. A small difference in per-token price can be outweighed by a model that needs fewer turns or less human correction.
What the “50% cheaper” claim compares
OpenAI’s September 22, 2026 release notes list GPT-6 Sol at $2 per million input tokens and $10 per million output tokens, and GPT-6 Luna at $0.10 input and $0.50 output. Comparing those standard rates with the previous GPT-5.6 Sol and Luna model pages gives a clear baseline: GPT-5.6 Sol was $4 input / $20 output; GPT-5.6 Luna was $0.20 input / $1.20 output.
Model transition | Input | Cached input | Output |
|---|---|---|---|
GPT-5.6 Sol → GPT-6 Sol | $4 → $2 | $0.40 → $0.20 | $20 → $10 |
GPT-5.6 Luna → GPT-6 Luna | $0.20 → $0.10 | $0.02 → $0.01 | $1.20 → $0.50 |
That means Sol’s listed rates are 50% lower across these token categories. Luna’s input and cached-input rates are 50% lower, while output is about 58.3% lower. These are token-price comparisons, not a promise that every project’s bill falls by the same percentage. Actual spend depends on input and output volume, cache hits, reasoning effort, retries, tool calls, and processing mode. See the official release notes, the GPT-5.6 Sol model page, and the GPT-5.6 Luna model page.
There is a second, separate “50%” in the API pricing documentation: Batch and Flex rates are 50% of Standard rates. That discount compares a processing tier with Standard for the same model. It is not the GPT-6-versus-GPT-5.6 price reduction. Standard GPT-6 short-context pricing is $10/$50 per million input/output tokens for Astra, $2/$10 for Sol, and $0.10/$0.50 for Luna. Prompts above 272K input tokens are charged at higher rates for the entire request, so long repository or document contexts deserve special attention.
Separate the agent from the model
Codex is OpenAI’s coding-agent product; GPT-6 is a model family. A coding agent combines a model with a harness for repository context, tools, permissions, and execution. “GPT-6 in coding agents” can mean choosing GPT-6 inside Codex or calling it through an API from another framework. It does not mean every agent uses GPT or that GPT-6 only runs in Codex.
OpenAI documents GPT-6 through the Responses API, with tool integrations for building agent workflows. Another agent can use GPT-6 if its provider interface supports the required API or a compatible adapter. MCP connects agents to tools and data; it does not by itself make the agent support every model.
Claude Code is a useful example. Anthropic’s setup guide says Claude Code uses Anthropic’s API by default; its documented alternate deployments include Claude models through Amazon Bedrock and Google Vertex AI. Its gateway guide describes an Anthropic-format endpoint. Anthropic’s published guides do not establish native GPT-6 support. A third-party gateway could translate requests, but that is adapter-dependent and needs compatibility testing.
Other agents do not need GPT. Each uses the models supported by its provider integration. Check API format, tool calls, context, streaming, and billing before assuming a model will work in a given agent.
Model roles in coding and agents
OpenAI positions Astra for the hardest end-to-end work, Sol for complex coding and agent workflows, and Luna for focused, high-volume tasks. All three list a 1.05-million-token context window and 128K maximum output. Selective retrieval still helps control cost and keep the agent focused.
When available in a compatible GPT-6 setup, Luna fits bounded chores such as issue classification, symbol extraction, small test fixtures, precise renames, and structured summaries. These tasks have clear success criteria and are easy to check.
Sol is a strong default for implementing a feature across a few files, debugging with tests, reviewing a pull request, or coordinating routine tools. It costs one-fifth as much per token as Astra at Standard short-context rates. Begin at medium reasoning and increase it when complexity calls for more analysis.
Astra fits broad or ambiguous work where a mistake is expensive: tracing a cross-service failure, planning an unfamiliar migration, or reviewing a sensitive change. Its token rate is higher, but it may reduce retries and human review. Measure that on your workload instead of assuming it will save money.
A practical routing pattern
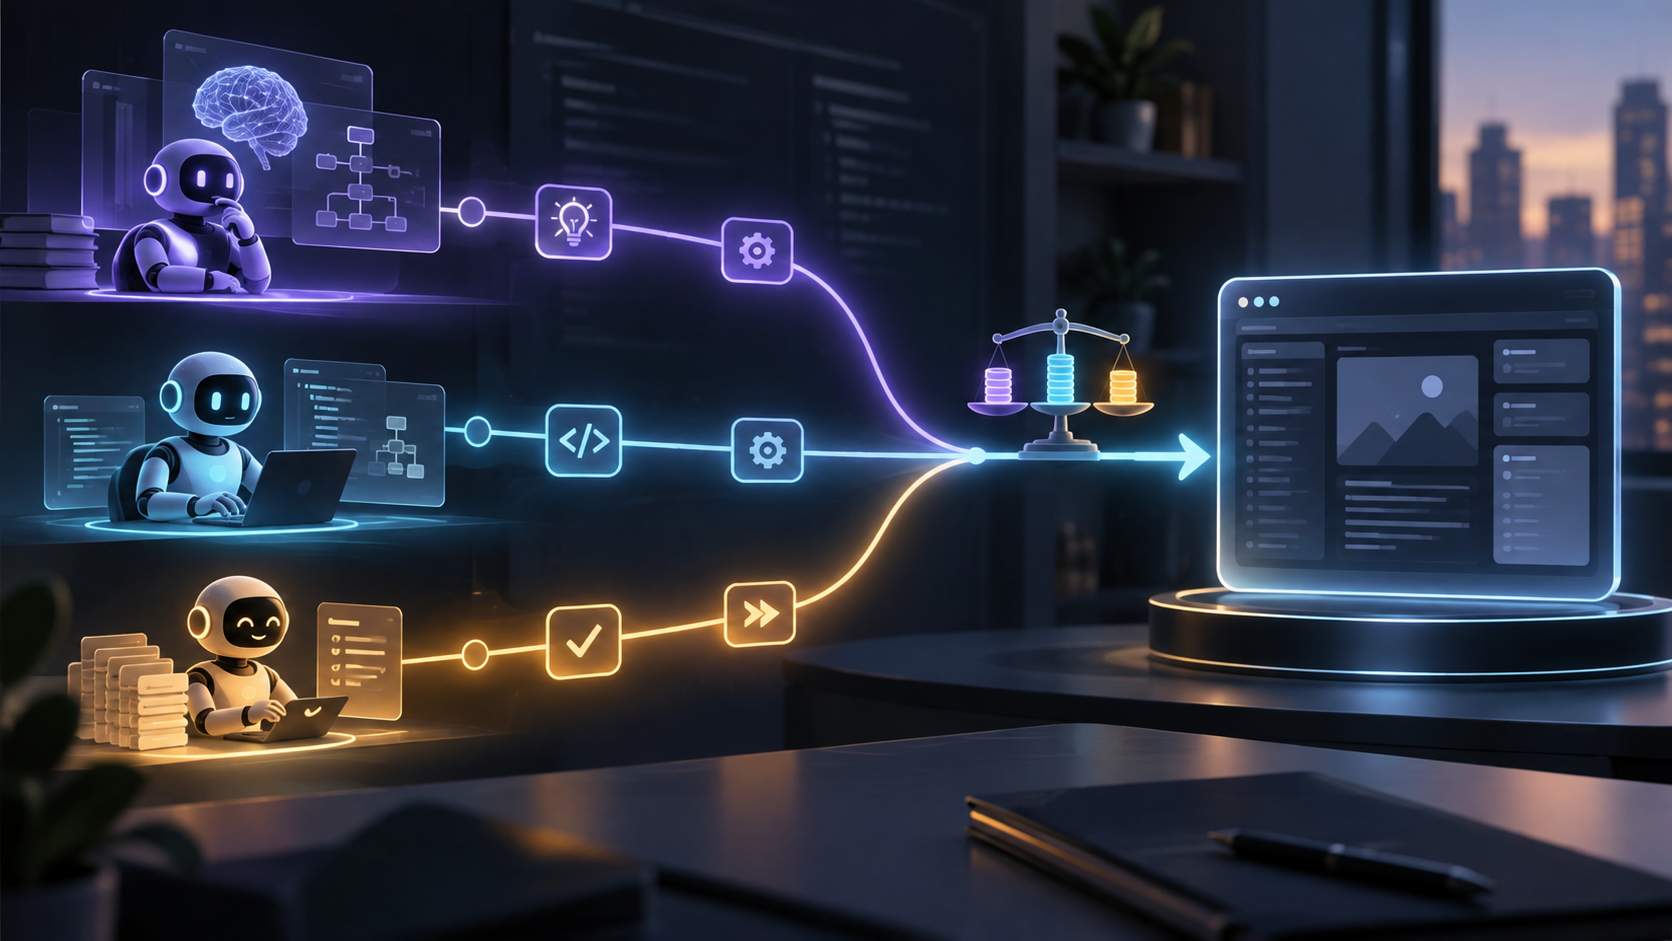
Route routine, testable work to Luna or Sol; escalate when the task becomes ambiguous, tests repeatedly fail, requirements conflict, or the decision has high impact. Keep human review for destructive commands and production changes.
In Codex, the configured model works within Codex’s tools and execution environment. In another framework, that product’s harness determines what the model can do. For API agents, track tokens, cache use, tool calls, retries, latency, accepted results, and review time. Compare cost per accepted task. A small evaluation set of real issues can reveal where each model meets your quality bar.
These metered API rates apply when an agent calls the OpenAI API; they are not ChatGPT or Codex subscription prices. ChatGPT sign-in and API-key billing are separate access paths.
Selection summary
Choose Luna when the task is narrow, repeated, and easy to check. Choose Sol as the everyday coding and agent default. Choose Astra when ambiguity, scope, or the cost of a wrong answer is high. The most useful cost optimization is usually routing work by difficulty and measuring cost per accepted result, while caching repeated context and avoiding unnecessary long prompts.
As of September 23, 2026, these rates and model positions reflect OpenAI’s published API documentation. Verify current pricing, availability, and limits before deployment.